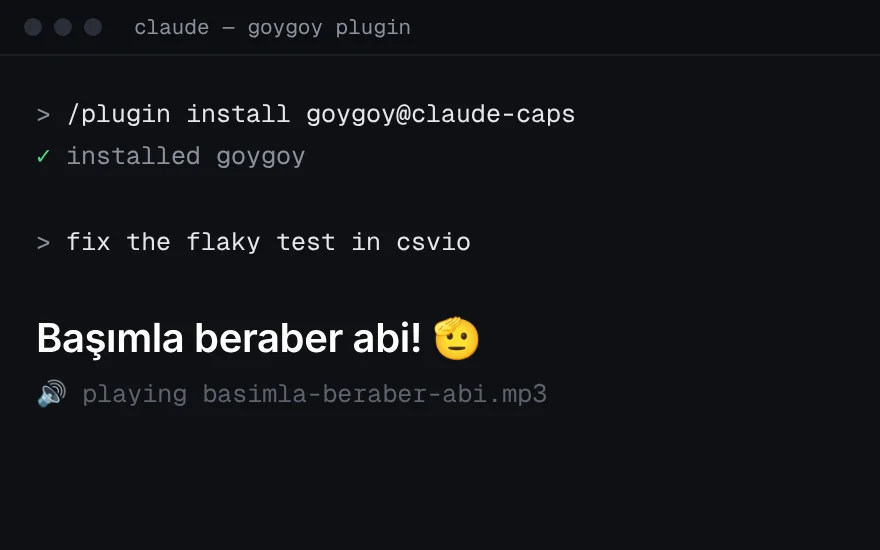
A queueing model of my day job: requests get dynamically batched onto MIG slices of one H100. Send a burst, then drop max batch to 1 and watch p99. Service times are modeled, not measured.
readabout.md–
About
I work on ML inference systems: deploying and optimizing the platforms that serve recommendation engines, search ranking, and increasingly AI agents in production. Most recently that meant a platform serving 100M+ users at over 1M requests per minute.
My work sits at the intersection of ML, systems, and infrastructure — vLLM and Triton for serving, and Kubernetes across cloud and on-prem. I care about the parts of ML that don't make it into most conference talks: p99 latency, GPU utilization, what breaks at 3am.
I'm a Google Developer Expert in Cloud AI. I co-organize GDG Istanbul and speak regularly at DevFest, Build with AI, and GDG events across Turkey and abroad, in both Turkish and English.
heads 0–11 →avg
These are the real attention weights of GPT-2 small reading the three paragraphs above, pooled from tokens to words. GPT-2 only looks backwards, so arcs always point to earlier words.
Each square is one head; rows are layers 0–11, and brighter squares look further back. Click one to switch.
Ran model serving for 100M+ users at 1M+ requests per minute with Triton and vLLM, on GKE and on-prem Kubernetes.
Reconfigured H100 GPUs with MIG so more models could share each card, for about 1.75x more serving capacity.
Designed the platform's deployment client, auth, active zone switching, and pipeline event notifications.
Built TensorRT conversion pipelines and tuned models from data science teams across the company; traced CPU inference bottlenecks down to memory latency with perf and TMA.
Benchmarked AMD MI325X against H200 for LLM and ranking workloads, and built an MCP tool and a set of Claude skills for the platform.
Turkcell2022 – 2024
AI & Analytical Solutions
readtalks.md–
Talks & Workshops
Selected talks
Sep 2026
Managing Agentic Systems on Google Cloud: From Deployment to Monitoring
Agents that turn a GitHub issue into a tested pull request
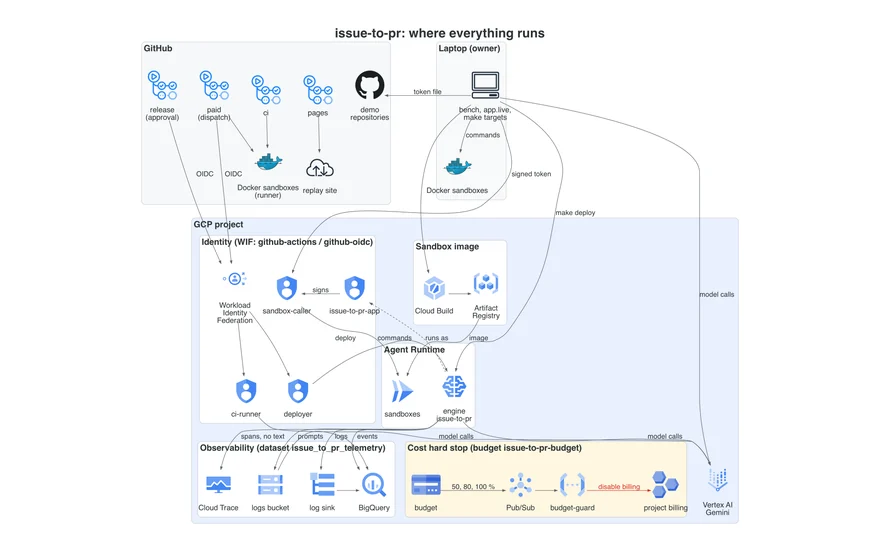
Planner, coder and reviewer agents in an ADK graph, routed by real diffs and test results instead of model claims. Commands run in sandboxes with no credentials or network, every run is cost-capped, and a human approves before a pull request opens. Deployed on Agent Runtime with keyless CI/CD. Watch recorded runs · architecture
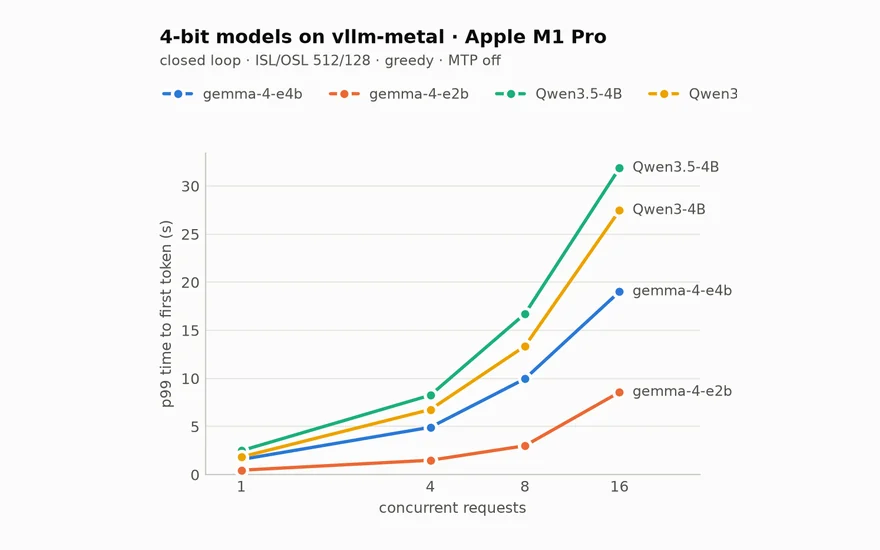
Four 4-bit models under AIPerf at 1 to 16 concurrent users. Bursty traffic made time-to-first-token about 5x worse than steady traffic at the same average rate, and the p99 knee came early. Scripts and raw per-request data included.
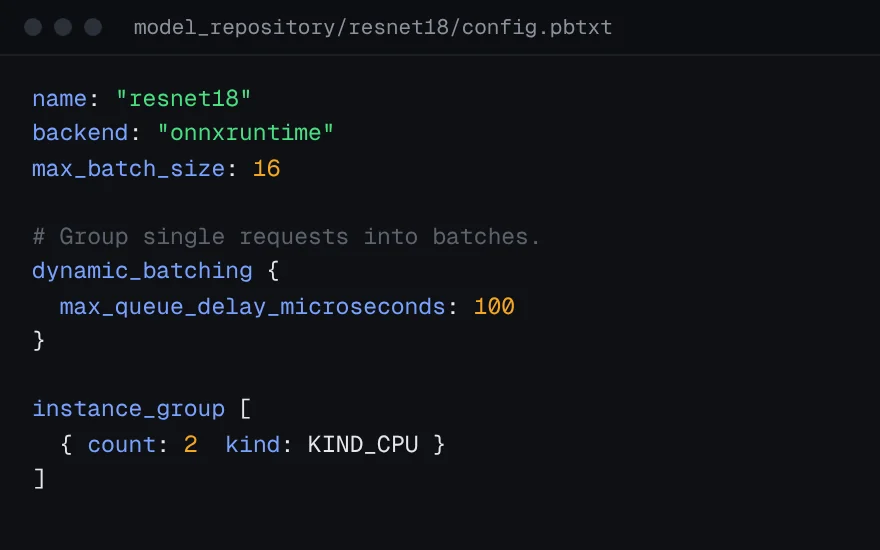
Serve a ResNet-18 with dynamic batching and two model instances, load test it with perf_analyzer, and deploy it to GKE. Runs on a laptop CPU. Companion code for my intro article.
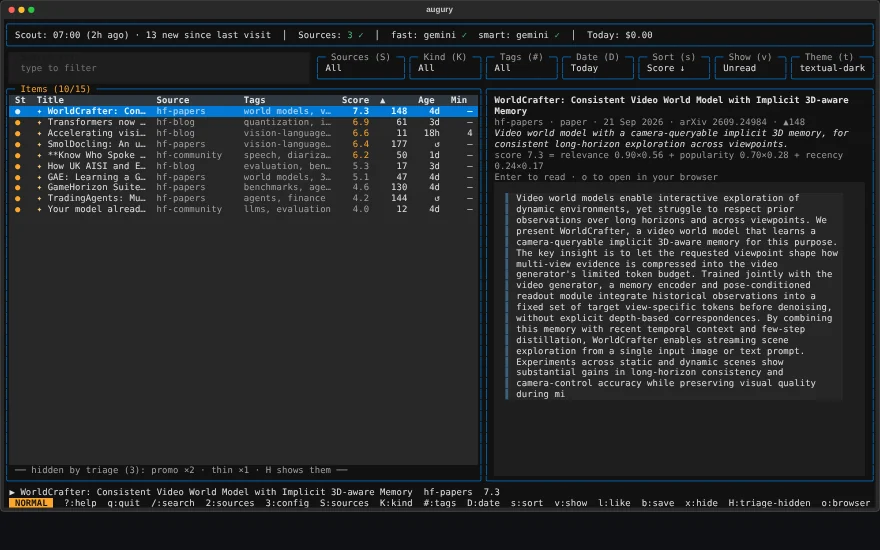
Collects new AI papers and posts every day, ranks them by what you like (with or without an LLM), and lets you read full papers without leaving the terminal. Includes hybrid search and Q&A over everything you've read.
I'm open to collaborations: talks and workshops, open-source work, and teams figuring out how to serve models or agents in production. Or just write to compare notes on inference at scale.
 Turkcell