Part 5 · The Right Setup
Goal: Reframe the problem on stationary return features as binary classification of the next day's direction (up = 1, down = 0), train it with BCEWithLogitsLoss, compare it with a majority-class baseline, and run 4-fold walk-forward validation.
Key ideas:
BCEWithLogitsLoss: Takes the raw score (logit) from the model's last layer, appliessigmoidinternally in a numerically stable way, and computes the binary cross-entropy loss.- Majority-class baseline: If 52% of training days are up days, a naive model that says "up" for every test day scores about 52%. We measure the model with both
AccuracyandBalanced Accuracy, which is sensitive to class imbalance. - Why is the honest result around 50–55%? Efficient markets, heavy daily noise and changing macroeconomic regimes make predicting direction from past prices alone very close to a coin toss.
Catch-up cell: 🔄 Catch up: Part 5 (run this if you skipped the previous part)
Step-by-step code walkthrough:
TODO 9 (sec5-cls-code): We train the direction classifier by calling the train_direction_classifier helper:
y_train_dir = train_df["up_day"].values.astype(np.float32)
y_val_dir = val_df["up_day"].values.astype(np.float32)
y_test_dir = test_df["up_day"].values.astype(np.float32)
# TODO 9 solution:
cls_res = train_direction_classifier(
x_train,
y_train_dir,
x_val,
y_val_dir,
x_test,
y_test_dir,
window_size=WINDOW_SIZE,
epochs=15,
seed=42,
)Then we run sec5-wf-code for 4-fold walk-forward validation and the confusion matrix:
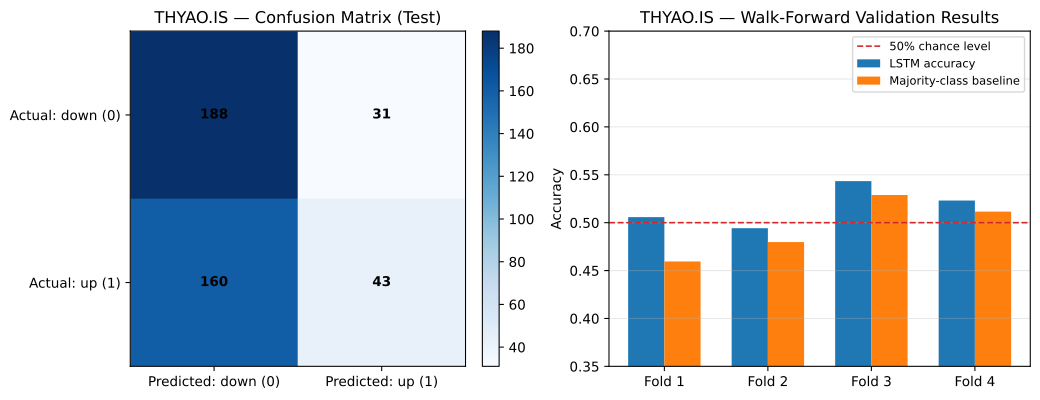
Expected output (measured values):
🎯 LSTM test accuracy       : 54.74%
⚖️ LSTM balanced accuracy   : 53.51%
📏 Majority-class baseline  : 51.90%
Walk-forward mean accuracy: 51.66%
Test accuracy is 54.74% against a 51.90% majority-class baseline, and the 4-fold walk-forward average is 51.66%. The test set has only 422 predictions, so the 95% confidence interval around 54.74% is about ±4.8 points (roughly 50% to 59.5%): this result cannot be told apart from a coin toss or from the baseline.
Troubleshooting (if this step fails):
ValueError: Target size ... must be the same as input size: Make sure you usetrain_df["up_day"].values.astype(np.float32)as the target vector. If variables are missing, run the🔄 Catch up: Part 5cell.